Independent Enterprise AI & Software Benchmarks
AIM Indices


Top 15 Answer Engine Optimization Tools
Google reports that AI Mode passed 1 billion monthly active users and that the Gemini app has 950 million. For brands, this means a ranking position no longer tells the whole story. Answer engine optimization (AEO) tools, also called generative engine optimization (GEO) tools, track whether and how AI systems such as ChatGPT, Google AI Overviews, AI Mode, Gemini and Perplexity mention a brand.
Compare and see the differences between AI Code editors, and CLI Agents
Identify the cheapest cloud GPUs for training and inference
Measure GPU performance under high parallel request load
Compare scaling efficiency across multi-GPU setups
Analyze features and costs of top AI gateway solutions
Compare the latency of LLMs
Compare LLM models input and output costs
Benchmark LLMs' accuracy and reliability in converting natural language to SQL
Compare the bias rates of LLMs
Evaluate hallucination rates of AI models
Evaluate multi-database routing and query generation in agentic RAG
Compare embedding models accuracy and speed
Evaluate leading open-source embedding models accuracy and speed
Compare retrieval-augmented generation solutions
Compare performance, pricing and features of vector DBs for RAG
Compare latency and completion token usage for agentic frameworks
Analyze performance of TikTok Scraper APIs
Evaluate the effectiveness of web unblocker solutions
Analyze performance of Video Scraper APIs
Analyze performance of AI-powered code editors
Compare scraping APIs for e-commerce data
Compare capabilities and outputs of leading large language models
See the most accurate OCR engines and LLMs for document automation
Benchmark search engine scraping API success rates and prices
Compare the OCRs in handwriting recognition
Compare tabular learning models with different datasets
Compare BF16, FP8, INT8, INT4 across performance and cost
Compare multimodal embeddings for image–text reasoning
Compare vLLM, LMDeploy, SGLang on H100 efficiency
Compare the performance of LLM scrapers
Compare the visual reasoning abilities of LLMs
Compare the orchestration performance of agentic frameworks
Compare the latency of AI providers
Compare multilingual embedding models for RAG
Compare reranker models for dense retrieval
Compare LLMs across software development tasks.
Compare how strong UI grounding models are.
AIMultiple Newsletter
1 free email per week with the latest B2B tech news & expert insights to accelerate your enterprise.
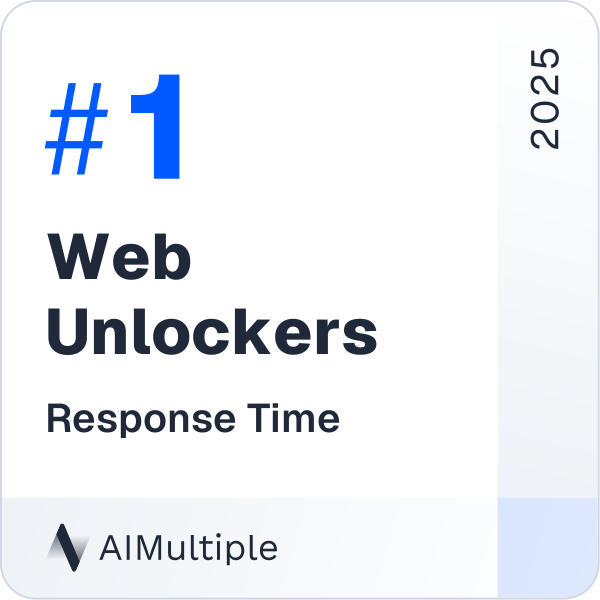
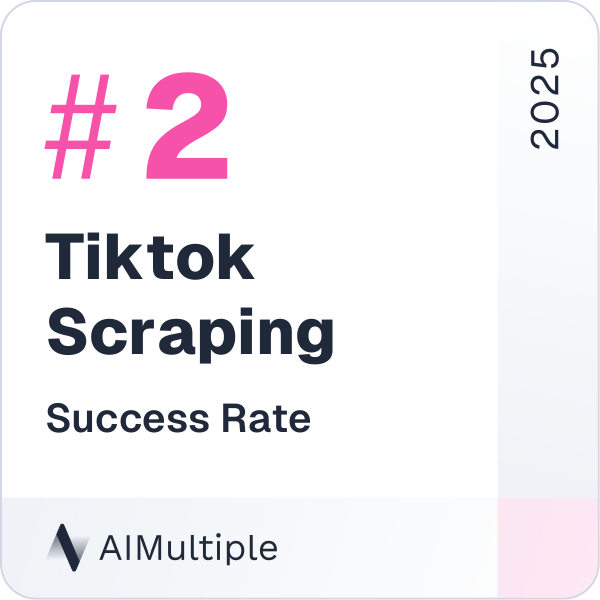
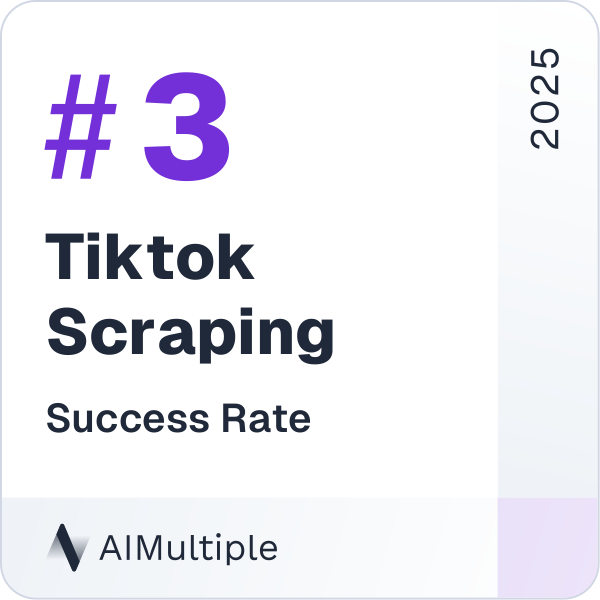
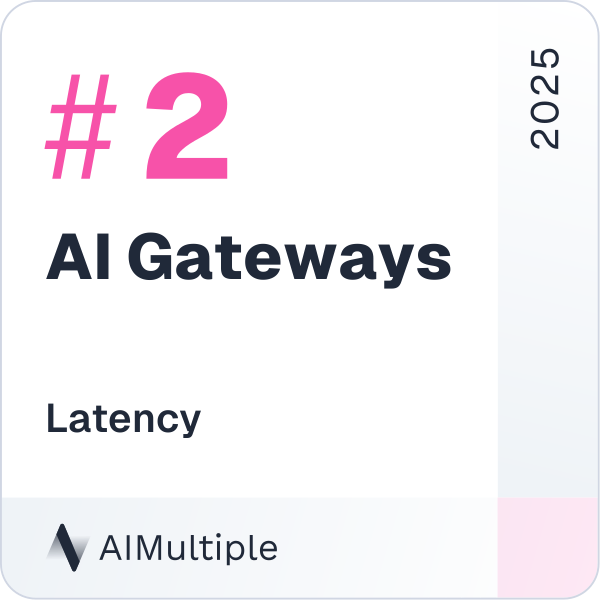
Badges from latest benchmarks
Enterprise Tech Leaderboard
Top 3 results are shown, for more see research articles.
Vendor | Benchmark | Metric | Value |
|---|---|---|---|
 Bright Data | 1st Success Rate | 100 % | |
 Apify | 2nd Success Rate | 99 % | |
 Decodo | 3rd Success Rate | 95 % | |
 Groq | 1st Latency | 2.00 s | |
 SambaNova | 2nd Latency | 3.00 s | |
 Together.ai | 3rd Latency | 11.00 s | |
 Zyte | 1st Response Time | 1.75 s | |
Bright Data | 2nd Response Time | 2.38 s | |
Decodo | 3rd Response Time | 3.43 s | |
Bright Data | 1st Overall | Leader |
Data-Driven Decisions Backed by Benchmarks
Insights driven by 45,760 engineering hours per year
60% of Fortune 500 Rely on AIMultiple Monthly
Fortune 500 companies trust AIMultiple to guide their procurement decisions every month. 4 million businesses rely on AIMultiple every year according to Similarweb.
See how Enterprise AI Performs in Real-Life
AI benchmarking based on public datasets is prone to data poisoning and leads to inflated expectations. AIMultiple's holdout datasets ensure realistic benchmark results. See how we test different tech solutions.
Increase Your Confidence in Tech Decisions
We are independent, 100% employee-owned and disclose all our sponsors and conflicts of interests. See our commitments for objective research.