


Generative IA Copyright: Law & Litigation

We reviewed court decisions, regulatory actions, and licensing agreements to answer three key questions about generative IA and copyright.
- Can copyright-protected data be used to train IA? There is no uniform legal approach. In the US, courts apply fair use on a case-by-case basis. District courts have reached different results depending on the purpose of the use, how the material was obtained, and its effect on existing markets.
- Are IA-generated works eligible for copyright protection? The answer depends on the jurisdiction. US copyright law requires human authorship. Some other countries have specific rules for computer-generated works.
- Who owns copyright in IA-generated work? Ownership depends on whether copyright exists and who the law recognizes as the author. No court has recognized an IA system itself as a copyright author.
1. Can copyright-protected data be used as training data?
United States
Sony Music Publishing and Warner Chappell sue Anthropic
In August 2026, Anthropic faced further copyright litigation from major music publishers. Sony Music Publishing and Warner Chappell filed suit in August 28, following an August action by Round Hill Music.1
Concord and UMG seek more than $3 billion from Anthropic
In January 2026, BMG and a group led by Concord Music Group and Universal Music Group also sued Anthropic.2
The Concord/UMG-led complaint alleges that Anthropic unlawfully obtained more than 20.000 copyrighted songs, lyrics, compositions, and sheet-music works. The plaintiffs claim potential statutory damages exceeding $3 billion.
Bartz v. Anthropic on IA training fair use
In Bartz v. Anthropic, the Northern District of California held that Anthropic’s use of books to train its models was fair use. The court separately held that acquiring and retaining millions of pirated books for a central library was not protected by fair use.
In July 2026, Judge Araceli Martínez-Olguín granted final approval of the $1,5 billion settlement in Bartz v. Anthropic and entered final judgment. Class counsel reported claims covering at least 91,3% of eligible works, while 350 valid opt-outs covered 1.802 works. The court rejected the requested $187,5 million attorney-fee award and approved approximately $101,56 million.3
The settlement resolves specified claims involving works included in the settlement class. It does not authorize future training or resolve separate claims involving model outputs or other copyrighted works.
Third Circuit reviews IA-training fair use
In June 2026, the Third Circuit heard oral argument in Thomson Reuters v. Ross Intelligence. The case is the first federal appellate proceeding to address whether using copyrighted material to develop an IA system qualifies as fair use. The panel focused on transformativeness and market harm. As of September 2026, no appellate decision has been issued.4
California AB 2013 requires training-data disclosures
California AB 2013 took effect in January 2026. Developers must publish information about the datasets used to train generative IA systems. Required disclosures include dataset sources, data types, whether copyrighted material is included, whether datasets were licensed or purchased, and whether they contain personal information.5
Kadrey v. Meta on IA training
In Kadrey v. Meta, another federal court rejected the plaintiffs’ infringement claims based on the evidence presented, including because they did not establish sufficient market harm.6
These rulings do not establish a general rule that all IA training is fair use.
France
France’s competition authority (Autorité de la concurrence) fined Google €250 million for using news articles without permission in training Gemini. This was a regulatory enforcement action, not a copyright ruling.7.
United Kingdom
UK government on removing protection for computer-generated works
In March 2026, the UK government published its report on copyright and artificial intelligence.
The report proposes removing the special copyright protection for computer-generated works under Section 9(3) of the Copyright, Designs and Patents Act. The provision remains in force unless Parliament changes the law.8
Getty v. Stability IA on model-weight infringement claim
In Getty Images v. Stability IA, the UK High Court rejected Getty’s secondary copyright infringement claim concerning Stable Diffusion model weights. The court did not consider the model itself to be an infringing copy for that claim.9
European Union
CJEU and its first generative IA copyright case
The Court of Justice of the European Union is considering Like Company v. Google Ireland, Case C-250/25. The Grand Chamber held oral arguments in March 2026.
The case addresses whether LLM training involves copyright-relevant reproduction, whether the EU text-and-data-mining exception can apply, and when chatbot outputs containing protected material may infringe copyright. As of September 2026, the case remains pending.10
Article 53 GPAI copyright compliance
Article 53 of the EU IA Act requires providers of general-purpose IA models to maintain a policy for complying with EU copyright law.
Providers must also publish a sufficiently detailed summary of the content used for training and address rights reservations made under Article 4(3) of the Digital Single Market Directive.11
Germany
GEMA wins copyright case against Suno
In July 2026, the Munich Regional Court ruled that IA music company Suno infringed copyrights in songs represented by German collecting society GEMA.
The court found that Suno lacked permission to process the protected songs and ordered the company to disclose revenue linked to the infringement.12
GEMA wins lyrics case against OpenAI
The Suno decision followed GEMA’s November 2025 judgment against OpenAI concerning copyrighted song lyrics reproduced through ChatGPT. OpenAI has appealed that decision to the Munich Higher Regional Court.13
Japan
Japan adopts generative IA transparency principle code
In August 2026, Japan’s Intellectual Property Strategy Headquarters published its Principle Code for the Protection of Intellectual Property and Transparency for the Appropriate Use of Generative IA.14
The Principle Code is non-binding and follows a comply-or-explain approach. It encourages IA businesses to disclose information about training processes, dataset categories, and data-collection methods.
Japan’s Copyright Act contains an exception that can permit the use of copyrighted works for information analysis, including some IA training.
The exception is subject to statutory limits, including whether the use allows enjoyment of the work’s expressive content and whether it unreasonably harms the copyright holder’s interests.
Singapore
Singapore on IA and copyright
In August 2026, Singapore’s Ministry of Law and Intellectual Property Office launched a public consultation on IA and intellectual property.
The consultation covers the computational data analysis exception, copyright-risk management when IA systems are deployed, and the role of human creativity in IA-assisted works.15
2. Are IA-generated works eligible for copyright protection?
India Rejects DABUS as an Author
In August 2026, India’s Copyright Office rejected Stephen Thaler’s application to register the DABUS-generated image “A Recent Entrance to Paradise”.16
The Copyright Office found that the image met India’s originality threshold but concluded that DABUS could not legally be recognized as the author.
Under Section 2(d)(vi) of India’s Copyright Act, the author of a computer-generated work is the person who causes the work to be created. The Copyright Office concluded that Thaler, rather than DABUS, fulfilled that role.
IA-assisted artwork received copyright protection
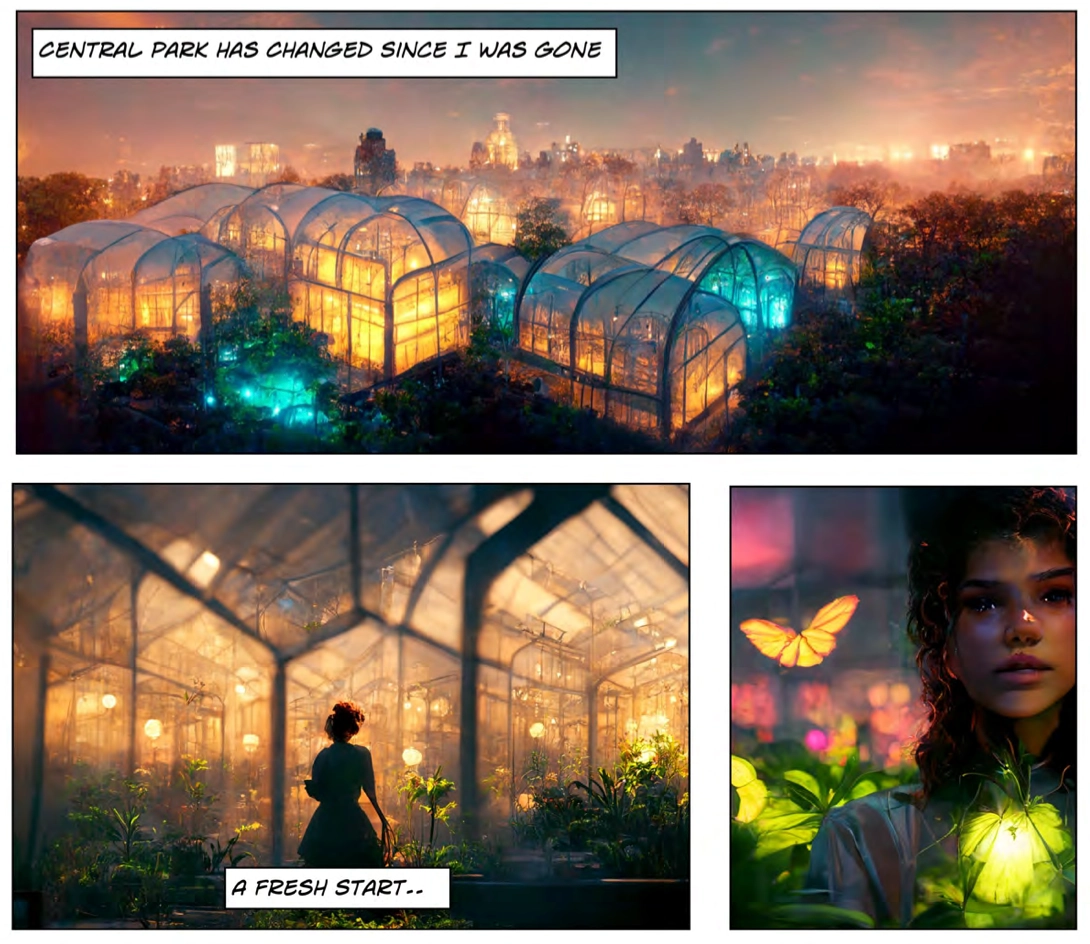
In September 2022, the US Copyright Office issued a registration for the comic book Zarya of the Dawn, created using the text-to-image IA tool Midjourney.17
The author clarified that the artwork was IA-assisted, not solely IA-generated. She structured the story, designed the page layouts, and made artistic decisions to arrange the elements alongside the IA-generated images.
Figure 1: Drawings from the last page of IA-generated comic book Zarya of the Dawn.
The award-winning Midjourney image was denied copyright protection
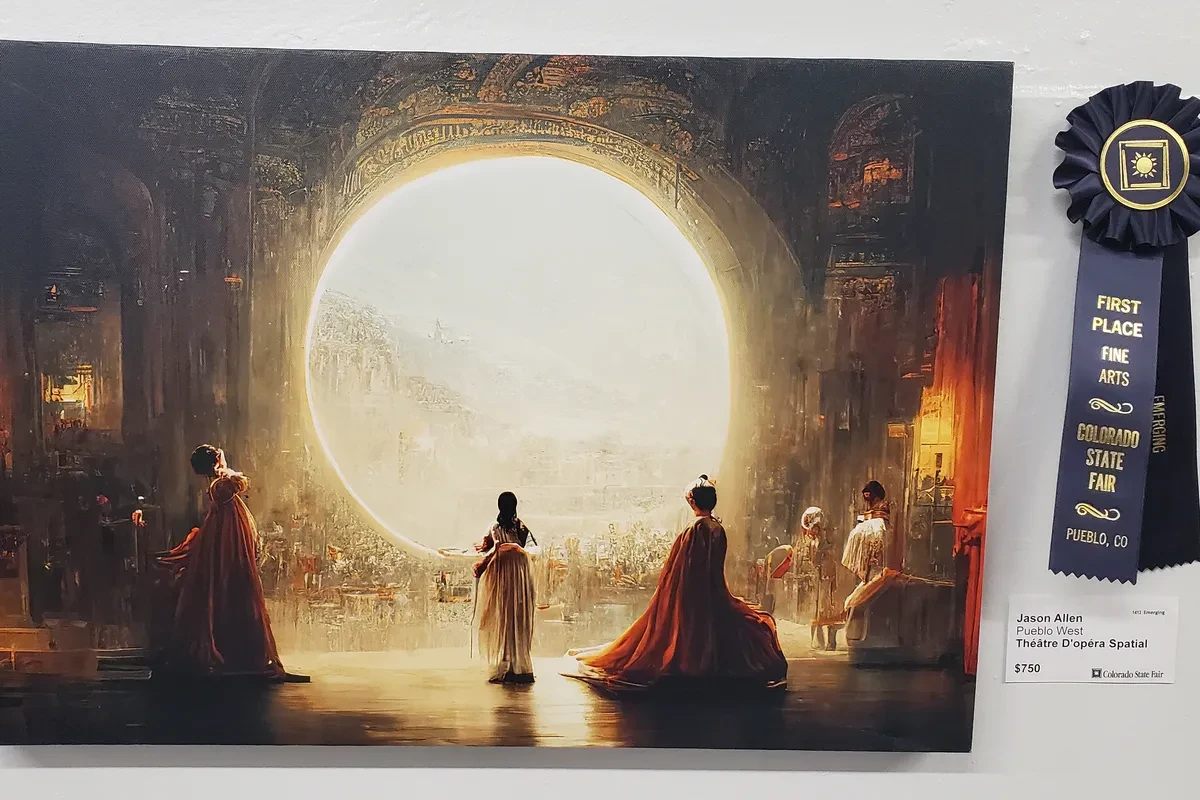
In 2022, Jason Allen won first place in the Colorado State Fair’s digital arts category with Théâtre D’opéra Spatial, an image created with Midjourney.
Allen used text prompts to generate the image, then made further edits before printing and submitting it. The award drew criticism from artists who argued that IA-generated works should not compete on the same terms as traditionally created art.
Figure 2: The award-winning IA-generated print Theatre d’Opera Spatial.18
In September 2023, the US Copyright Office refused to register Jason Allen’s artwork as a copyrighted work because the image contained more than a minimal amount of IA-generated material.
Allen argued that he had used hundreds of prompts and later edited the image in Photoshop. The Copyright Office concluded that the Midjourney-generated elements were not the product of human authorship.19
3. Who owns the copyright in IA-generated work?
In most countries, copyright law assigns ownership to the creator of a work. When IA produces the work, the question of who the creator is and, therefore, who owns it has no settled universal answer.
- United Kingdom: The Copyright, Designs and Patents Act provides that, for a qualifying computer-generated work, the author is the person who undertakes the arrangements necessary for its creation.
- India: For a computer-generated work, the statutory author is the person who causes the work to be created.
- United States: IA-generated material without sufficient human authorship is not protected by copyright. Where an IA-assisted work contains copyrightable human contributions, ownership follows the rules applicable to those human authors.
For more on generative IA
- Generative IA in Healthcare: Benefits, Challenges, Potentials
- Generative IA in Fashion: 5 Use Cases with Case Studies
- Top 5 Use Cases of Generative IA in Education
 Adicionar como fonte preferencial
Cite esta pesquisa
Escolha o formato adequado ao local onde você vai publicar. Colar a versão com link no seu CMS preserva o backlink.
@misc{dilmegani2026,
  author = {Dilmegani, Cem and Ermut, Sıla},
  title  = {{Generative IA Copyright: Law & Litigation}},
  year   = {2026},
  month  = sep,
  howpublished    = {\url{https://aimultiple.com/generative-ai-copyright}},
  note   = {AIMultiple. Acessado em 3 setembro 2026}
}
Registro de alterações
14 atualizaçõesRemovidas as seções de acordos de licenciamento de IA, boas práticas e glossário.
A seção EUA foi atualizada com novas decisões e detalhes de litígios.
Atualizada a seção "Dados protegidos por direitos autorais podem ser usados como dados de treinamento?" com novas informações sobre uso justo nos EUA.
Links de referência
O trabalho de Cem na AIMultiple foi citado por publicações globais líderes, incluindo Business Insider, Forbes, Morning Brew e Washington Post, por empresas globais como Deloitte e HPE, ONGs como o World Economic Forum e organizações supranacionais como a European Commission. [1], [2], [3], [4], [5]
Ao longo de sua carreira, Cem atuou como consultor de tecnologia, comprador de tecnologia e empreendedor de tecnologia. Ele aconselhou empresas sobre suas decisões de tecnologia na McKinsey & Company e na Altman Solon por mais de uma década. Ele também publicou um relatório da McKinsey sobre digitalização.
Ele liderou a estratégia de tecnologia e as compras de uma operadora de telecomunicações, reportando-se ao CEO. Ele também liderou o crescimento comercial da empresa de deep tech Hypatos, que atingiu uma receita recorrente anual de 7 dígitos e uma avaliação de 9 dígitos partindo do zero em 2 anos. O trabalho de Cem na Hypatos foi coberto por publicações de tecnologia líderes como TechCrunch e Business Insider.
Cem fala regularmente em conferências internacionais de tecnologia. Ele se formou como engenheiro da computação pela Bogazici University e possui um MBA pela Columbia Business School.

Ela trabalhou anteriormente como recrutadora em empresas de gerenciamento de projetos e consultoria. Sıla possui mestrado em Psicologia Social e bacharelado em Relações Internacionais.


Seja o primeiro a comentar
Seu endereço de e-mail não será publicado. Todos os campos são obrigatórios. Os comentários são deixados em seu idioma original.